MongoDB Schema Design: Best Practices for Beginners
Last updated on Nov 18, 2026
Philosophy of Document Model Introduction
As a developer you generally have to change your mindset when moving from relational databases to MongoDB and NoSQL database design. In traditional relational databases data is regulated by data normalisation rules. The data are spread over a number of discrete tables, linked together by primary and foreign keys and assembled at query time by complex join operations. This relational normalisation is (primarily) intended to reduce data redundancy and save space, a very important consideration in the first decades of enterprise computing when storage was very expensive and memory was limited.
MongoDB has a different way of storing and retrieving data. Instead of rows and tables, MongoDB stores data in documents and collections. It uses a flexible format called BSON which is basically a binary form of JSON . Fundamentally, MongoDB schema design is an application-centric way of modelling. It is not about how to normalise data into strict structural categories . It is about how the app reads and writes data . ( MongoDB developer ) Group together the data that is accessed together.
This change is fundamental . The most important architectural decisions are performance, query speed and scalability . By mapping the database schema to the application's own user stories and read patterns, developers are able to avoid expensive, computationally heavy joins on every read request. But the flexibility is a double-edged sword for new users. By default MongoDB is not schema-enforced, and it’s easy to fall into traps that look like relational habits or create performance bottlenecks as datasets grow. At the heart of MongoDB schema design is knowing the basic choice between embedding and referencing, learning the common patterns, and trying to avoid the anti-patterns that can adversely affect your MongoDB performance.
Since there is no clear schema within the structure of the database, it can be extremely difficult for one to fall into either of two categories of either working as if it were a relation-based database or becoming slow in terms of its performance due to the growth of the data sets. Should you be new to this and you wish to learn more about how to use them, then perhaps a mongodb learning path could help you.
The Core Dilemma: Embedded or Referenced?
In MongoDB, any relationship between data comes down to one architectural question: do you want to embed related information into a single document or do you want to break it up into separate documents and link them via references? That decision will affect the scalability of your application, the cleanliness of your queries and the performance of your system under heavy production loads.
Power Embed
Embedding means you store related data structures as sub-documents or arrays inside the parent document. For example, an eCommerce site where a customer document has an embedded shipping address or an order document has an array of line items.
The main benefit of embedding is that it makes retrieval more efficient. You get the parent document from database and have all the related information in one round trip. No joins to process on the server end. No secondary queries to run. MongoDB also supports atomic writes at the document level. Changing an embedded subdocument or array element is an atomic operation, which means it is either all done or all undone. This is strong consistency, without the cost of distributed transactions across multiple documents.
Embedding is best suited for “one-to-few” relationships where the nested data is closely related to the parent entity, is small and bounded in size, and is almost always read at the same time as the parent.
The Power of Referrals”
Instead referencing is the act of storing related data in different collections, and linking them with unique identifiers . The identifiers are usually unique object identifiers, which link from one document to another. Instead of putting all the reviews that a product receives into the product document, each review is a document on its own, with a reference field pointing back to the unique identifier of the parent product.
References are similar to normalisation concepts in relational databases, but are used selectively in MongoDB. It is the right architect choice if related data is large, grows unbounded, changes itself frequently or is shared across multiple parent documents. For example, if a product can be bookmarked by thousands of users, embedding the list of users in the product document will soon exceed size limits and cause constant write conflicts. We reference documents so that they can be lean and manageable.
Designing for workload applications
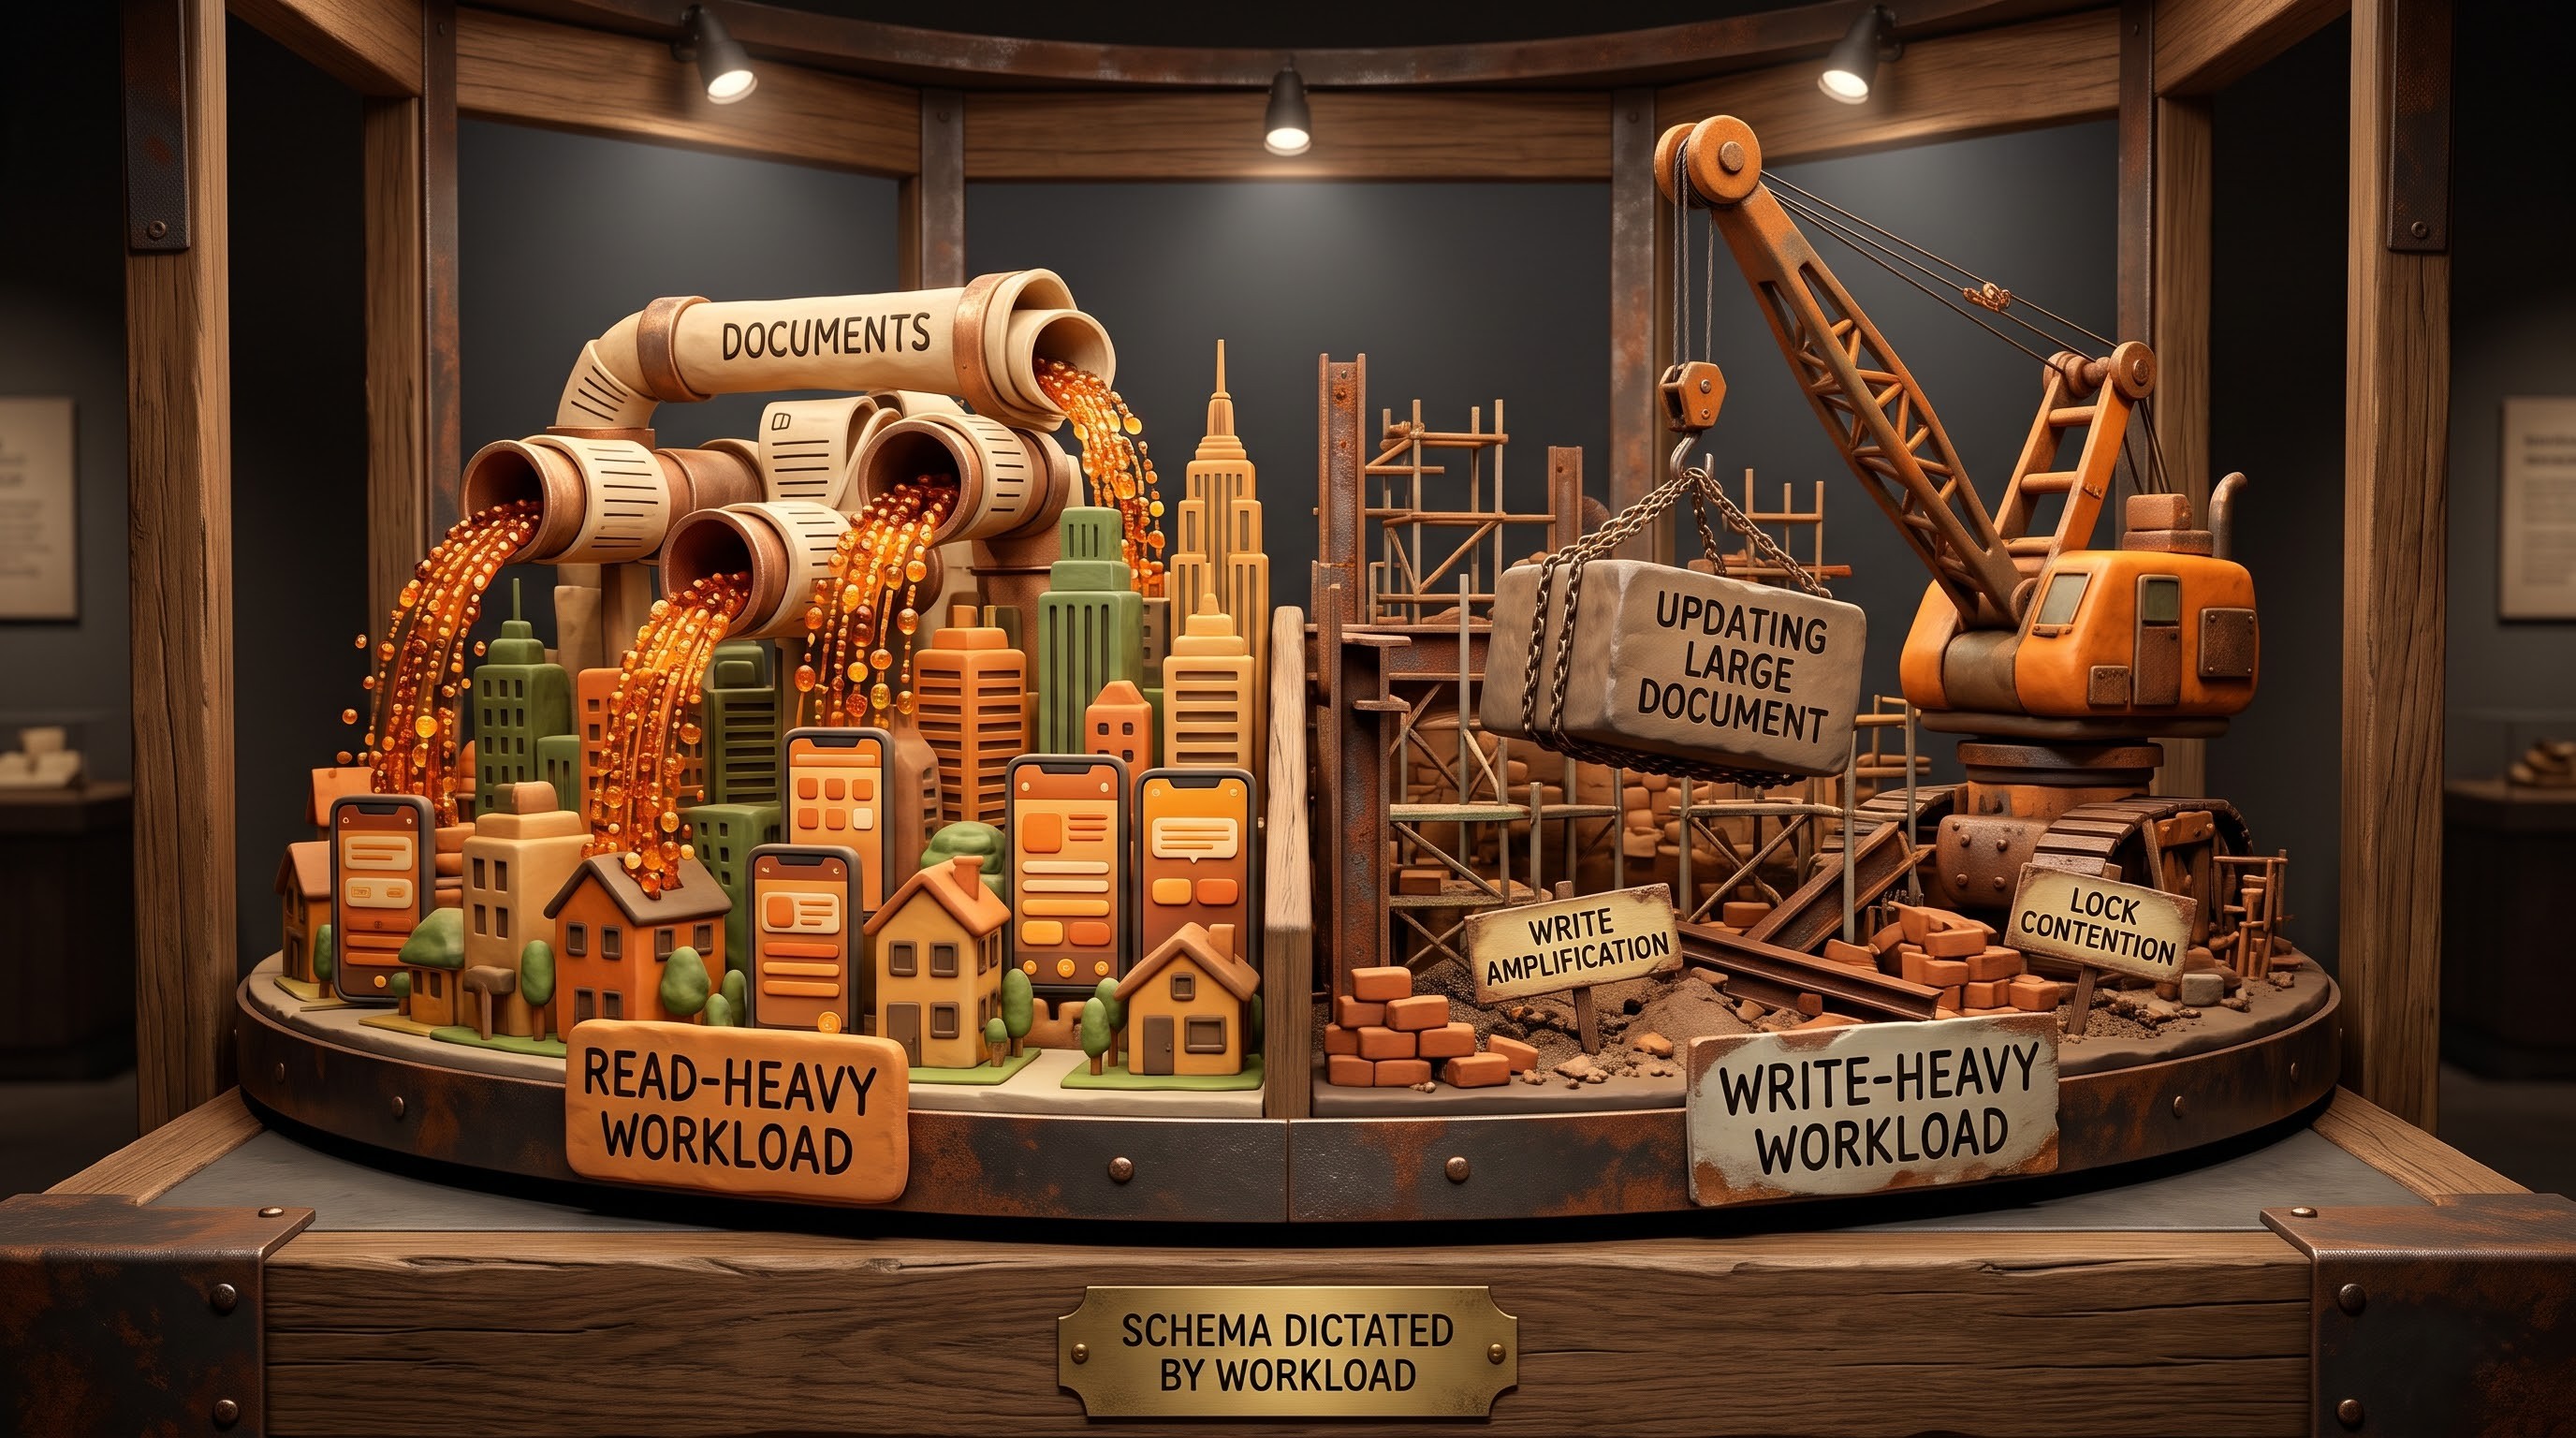
The mistake that beginners often make is to design the database schema only from the abstract entity-relationship diagrams, without taking into account the real behaviour of the software. MongoDB says your schema is dictated by your workload.
You cannot write a single line of code to create a database before mapping out the read and write patterns of your application, only then can you design an effective schema. Enumerate the queries that your application will execute most often. Are you building a social media feed with users reading posts with thousands of comments? Or are you building an admin dashboard where summary analytics are calculated once per day? Are you read-heavy and need fast retrieval? Or are you write-heavy with data coming in all the time from thousands of Internet of Things sensors?
If your workload is read-heavy, a common and very effective practice is to duplicate data or embed related records. The performance payoff during reads is enormous. Even if that means storing the user's username inside their comment docs instead of forcing a lookup each time a comment is rendered. In contrast, write-heavy workloads benefit from normalised referencing structures, in an effort to reduce the write amplification and lock contention that occurs when large bloated documents have to be rewritten in full on disc for minor updates.
Physical Limitations: Limits on the Size of Documents
If you are new to the flexibility of document databases, you should be aware of the hard physical constraints imposed by the underlying storage engine. MongoDB enforces a size limit of 16 megabytes for each of its stored BSON documents. One text-based record takes 16MB of space which is a lot, but ignoring this limit can lead to catastrophic application failures.
That 16 megabyte limit is not a ceiling but a guardrail of design. If your app design allows for unlimited growth in a single document (e.g. appending log entries, audit trails or unmoderated user comments into an internal array), you will at some point cross the line. If a write operation tries to push a document over this limit, MongoDB rejects the whole write, which can lead to application errors and potential data loss.
Therefore, embedding is only used when the data size is strictly bounded. If the entity has a variable number of children records, that can grow indefinitely during its life, the children records should be stored in a separate collection and linked by references or specialised design patterns.
Advanced design patterns and strategic de-normalization
These are just two simple ways you can design your schema in MongoDB: embedding and referencing. There is a whole set of intermediate patterns that solve common scaling problems without losing read performance.
The Calculation Pattern
Many applications read some values much more frequently than they update them. For example, performing these calculations on the fly for each read query, such as summing total sales figures for an order, or calculating average user review scores, wastes valuable CPU cycles. This is addressed by the Computed Pattern, which pre-computes the aggregated values and stores them in the parent document. A background process or application logic updates the precomputed total when a child record is changed. This shifts computing from the read time to the write time. That means blazing fast read performance for end users.
Creating buckets
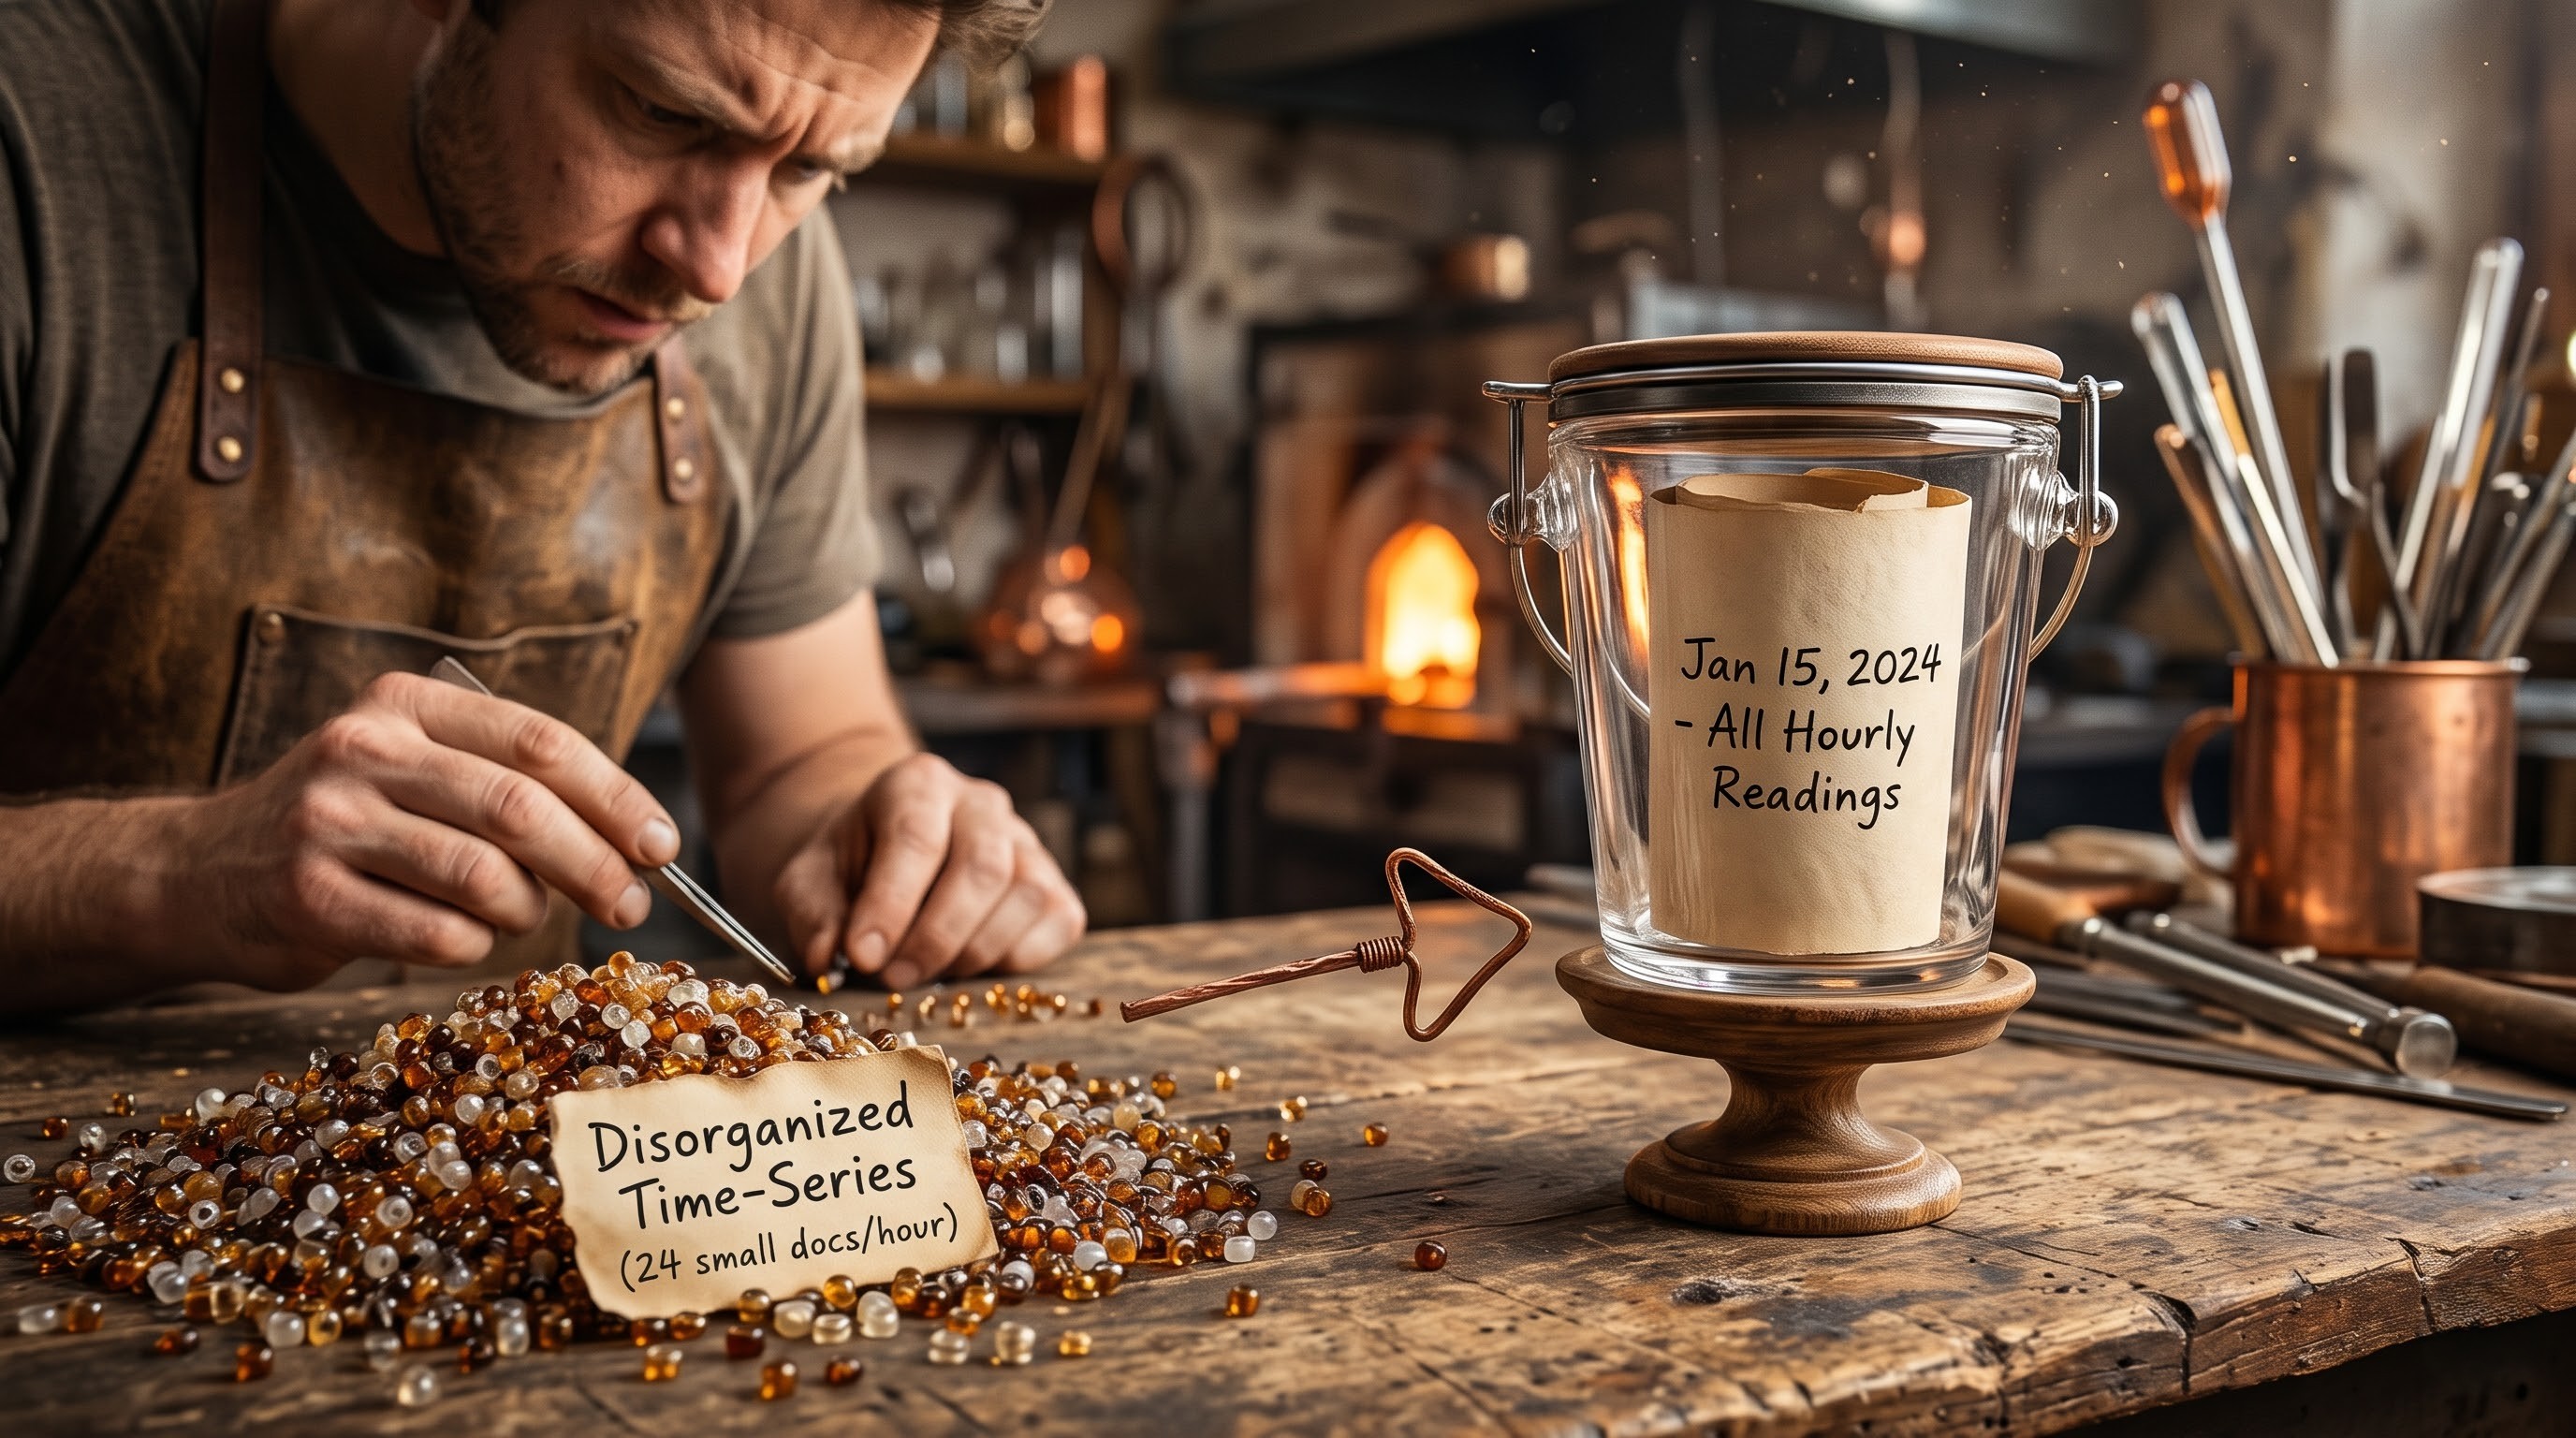
If each event is stored as a separate document, the number of small documents grows exponentially, degrading indexing performance and wasting storage space. This is especially true for time series data such as sensor or financial tick data. The Bucket Pattern utilises a logical boundary, such as a time window or a maximum count limit, to consolidate a group of related events into a single document. So instead of 24 documents per hour, the device recorded a temperature reading, you now have one document that contains an array of all the readings for that calendar day. This keeps document sizes optimal, the total number of documents in the collection minimal, and it dramatically improves query speed over historical ranges.
The Subset's Pattern
Imagine a parent document that has a huge list of child items (think of a user with thousands of transaction records), but the user interface only ever displays the ten most recent child items. Put everything in place and you have bloated documents that put pressure on memory caches. The Subset Pattern addresses this by splitting the relationship. The main parent document only contains a small subset of the most accessed items (e.g. the last ten transactions) with the full historical record stored in a separate collection. This gives the app the best of both worlds, lightning fast first page loads with the most relevant data, and secondary queries only when deep history is explicitly requested.
Common Schema Anti-Patterns: Recognising and Avoiding Them
Even with the best intentions, beginners often find themselves falling into the repeated structural traps that degrade the database performance. Identifying these anti-patterns early is key to a healthy and scalable database architecture.
Anti-Pattern “Unbounded Array”
The section on document size limits describes why it is a bad anti-pattern to allow an array in a document to grow without any programmatic restriction. Maybe keeping tabs on every user click. Or save unlimited messages in one document room. Or collecting notifications for ever. Unbounded arrays are always larger than the sixteen megabyte limit and slow down indexes. Make sure a relationship is really bounded before you decide to embed. Growth is an endless well of use or reference.
The Big Document Anti-Pattern
Documents bloat when they are filled with lots of extraneous text, binary payloads or deeply nested metadata that is rarely accessed along with the primary record. MongoDB’s storage engine is designed for huge in-memory caching, which means it can serve frequent queries straight from RAM, rather than slower physical disc. The sheer number of documents, and the presence of redundant data reduce the number of documents that can be stored in the available cache memory. This makes the database engine do expensive disc reads, which slows down the whole system. Keep documents only for the time necessary for primary access workflows.
Too many joins on a server
Mongo DB has powerful lookup stages in its aggregation pipeline to join data across multiple collections. But using MongoDB as a drop in replacement for relational foreign key joins on every single query is an anti-pattern. Too many lookups make the query more complex, increase processing overhead on the server, and negate the basic performance advantages of the document model. If your app is doing multi-collection joins constantly for normal read operations your schema is probably over-normalised and should be reconsidered for strategic embedding or denormalisation.
Validation, Indexing and Operations Best Practices
A great schema is not just the shape of the document, but the operational guardrails you put in place to keep the data clean and the queries fast over time.
Strategic Indexing for Query Performance.
If the queries are not indexed, even a perfect schema will be crawled. Indexes are special data structures that allow MongoDB to quickly find documents without having to examine every document in a collection. If you are a beginner, be sure that fields that are often used in query filters, sorting and equality checks are properly indexed.
But there has to be some balance in the indexing. The index occupies disc and memory space. For each write operation ( insert , update , delete ) the database engine updates all indexes that are involved in the write . Unnecessary, redundant or rarely used indexes degrade write performance and add to storage overhead. Statistics on query execution must be monitored to know if the indexes are effectively being used by the application query receiving many queries. Persons who want to become experts on indexes and the tuning of schemas are advised to take part in mongodb training online.
Schema validation for data integrity
MongoDB’s schema-less flexibility is great for fast iteration in early development, but there are huge upsides to defining structural rules in production environments. You can add MongoDB JSON Schema validation rules directly on a collection. The rules allow developers to require fields, limit data types and validate incoming payloads at the database level. Validation rules are a safeguard against malformed data getting into your collections due to stray bugs in your app, or inputs coming from outside your app in ways you didn't expect. And this is what counts as your project grows.
Iterative refinement and performance tracking
Designing a database schema is more often than not not a one-off, static exercise you do at the beginning of a project. Over time, as applications evolve, user behaviours change, and data volumes grow, access patterns change. Modern database management tools and monitoring dashboards provide you with constant insight into performance, pointing out slow queries, missing indexes and structural inefficiencies that are just starting to emerge. Keep testing your schemas with real workloads and improve your schema over time. That means that you are going to have a strong and flexible MongoDB architecture that scales smoothly in the future.
Adopting the future of scalable architecture
The need for flexible, performant data layers becomes even more pressing when modern software applications scale to handle massive global traffic and real-time analytics for microservice-driven ecosystems. Traditional relational databases work well with enterprise resource planning systems with a rigid schema, but they often don’t work for rapid, iterative feature rollouts common to modern web and mobile products. MongoDB addresses this shortfall with a document-based architecture that corresponds to the native data structures used by modern programming languages such as JavaScript objects and JSON payloads. This alignment in architecture reduces the friction between application code and database storage, which allows development teams to ship features faster and iterate with confidence.
But moving from theory to real production implementation demands a significant cultural change within engineering teams. Developers need to unlearn the reflex that everything goes in its own table. Instead they need to know how their software really uses data. When designing a schema, you need to think about all the queries that an API endpoint will run, all the background sync jobs, and all the aggregation routines on a dashboard. When the schema design gets translated into the application logic, separate from the database management system, it is possible for the developers to use the actual power of NoSQL technology. It is at this point when the need arises for the developers to enroll in the mongodb training program to gain practical insight into the subject matter.
Also it is important to create a collaborative environment between the software engineers and database administrators and system architects for long term success. Architectural decisions taken early in the prototyping phase will be a solid foundation or a bottleneck that will require a costly refactoring when terabytes and petabytes of data are at stake. Regular performance audits, detailed documentation of access patterns, and internal design reviews will help ensure that your database scales gracefully as your user base grows. At the end of the day learning MongoDB schema design is not about learning syntax or memorising design patterns but developing a mindset geared toward performance, flexibility and workload driven architecture.
Conclusion
The key to successful MongoDB schema design is a fundamental shift of perspective from the rigid normalisation rules of traditional relational databases to an application-driven modelling approach. As we’ve seen throughout this guide, the real power of MongoDB lies in its flexibility and its ability to allow database structures to map directly to the specific read and write patterns of your software. This lets developers know when to embed related data for optimal retrieval efficiency and when to use referencing to enable unbounded growth. This allows the construction of systems that scale nicely, even under heavy production loads.
But structural freedom demands discipline and premeditation. The beginner needs to be very careful to respect physical guardrails such as the sixteen megabyte BSON document limit and avoid common architectural pitfalls such as unbounded arrays, bloated documents and over-use of server-side join operations. Developers are able to solve tough scaling challenges and achieve blazing fast query performance with advanced intermediate patterns such as the Computed Pattern, the Bucket Pattern and the Subset Pattern. A good schema, smart indexing, and strong JSON schema validation will also go a long way to keeping your data efficient, tidy and safe as your app grows.
In conclusion, building a database design is more of an evolution than a completion process. This is because the behavior of users, the volume of data, and the features of applications keep on evolving and hence the need to have an evolving database design. The best way to maximize the full capacity of MongoDB is through workload analysis and performance measurement.