ServiceNow AIOps: Using AI to Improve IT Operations
Last updated on Oct 19, 2026
Today, corporate IT systems play a dominant role because they are no longer inferior to the possibilities of manual management. As a joke, IT infrastructure development, combinative structure, micro-services, container-based solutions, and transient computing led to immense volumes of operational data creation. The staff working for the companies has to manage immense amounts of operational data with numerous logs, pointers, events, and traces produced every day.
In companies that are using IT operation management systems, huge data flow causing alert fatigue, long queues, mutual blame of disparate departments, and MTTR increase is observed. In conditions where normal business functioning is impossible, the search for the vital information among numerous connected alarms takes so much time that people think that they better comply with the law rather than contribute to business.
ServiceNow AIOps is the answer to the structural problems characteristic of IT operations. It runs on the Now Platform, well integrated with IT Operation Management. The Copernican axiom is to extrapolate from extra large data on machine learning, AI, and natural language processing with files present in the operational activities of an enterprise. Instead of presenting different tool monitoring dashboards, ServiceNow will combine raw telemetry with context data from configuration items, SLAs, historical incidents, and automatic remediation techniques. This results in a shift from responses to crisis solutions towards automatic and proactive operations management.
The main Issues in Modern IT Operations
In order to understand the impact of ServiceNow AIOps, it is critical to have an idea of the structural issues that provide challenges for classical IT operations.
Isolation of data and the use of non-integrated tools
Organizations generally have more than one monitoring tool in place. The typical enterprise system environment can also have different monitoring tools for different aspects of the monitoring process such as network monitoring tools, application performance monitoring tools, monitoring tools for cloud infrastructure, monitoring tools for container orchestration, and monitoring tools for monitoring the end-users experience. Each monitoring tool has its own set of unique features about it such as their own alerts, their own naming conventions and their own severity levels. If there is not a monitoring solution that integrates the use of all the telemetry streams, the operation teams will end up wasting a lot of time looking through several dashboards in order to determine what has happened.
Eliminating Alert Fatigue and Static Thresholds
A majority of legacy monitoring solutions depend on inflexible static thresholds. For instance, if the CPU usage goes over 85 percent, an alert is generated. However, high usage of the CPU when the database is being backed up is not a cause of worry. If the CPU goes and processors transactions then that could be an issue. Static thresholds are unable to tell the difference between cyclical activity and real deterioration of the process.
Manual Approach of Identifying Root Cause and Triage Systems
A major service failure in the operations of an organization gives rise to several other alarms in microservices, databases, load balancers, and networking devices. To identify the root cause of failure, it is necessary to check logs, analyze the relevant parameters and perform multiple triage calls since the investigation process is mostly performed by people who increase the time it takes to restore the system.
ServiceNow AIOps Architecture Overview
ServiceNow AIOps is more than just the use of machine learning algorithms in a self-sufficient database because its essence lies in the integration into the Common Services Data Model and the Configuration Management Database.
Layer of Data Collecting and Processing
This platform is capable of collecting any operating data from almost any monitoring service, cloud provider, or software-defined infrastructure. ServiceNow AIOps can receive events, performance metrics, system logs, and distributed traces through numerous native connectors, API-based solutions, and the ServiceNow Agent Client Collector.
Understanding CMDB and CSDM
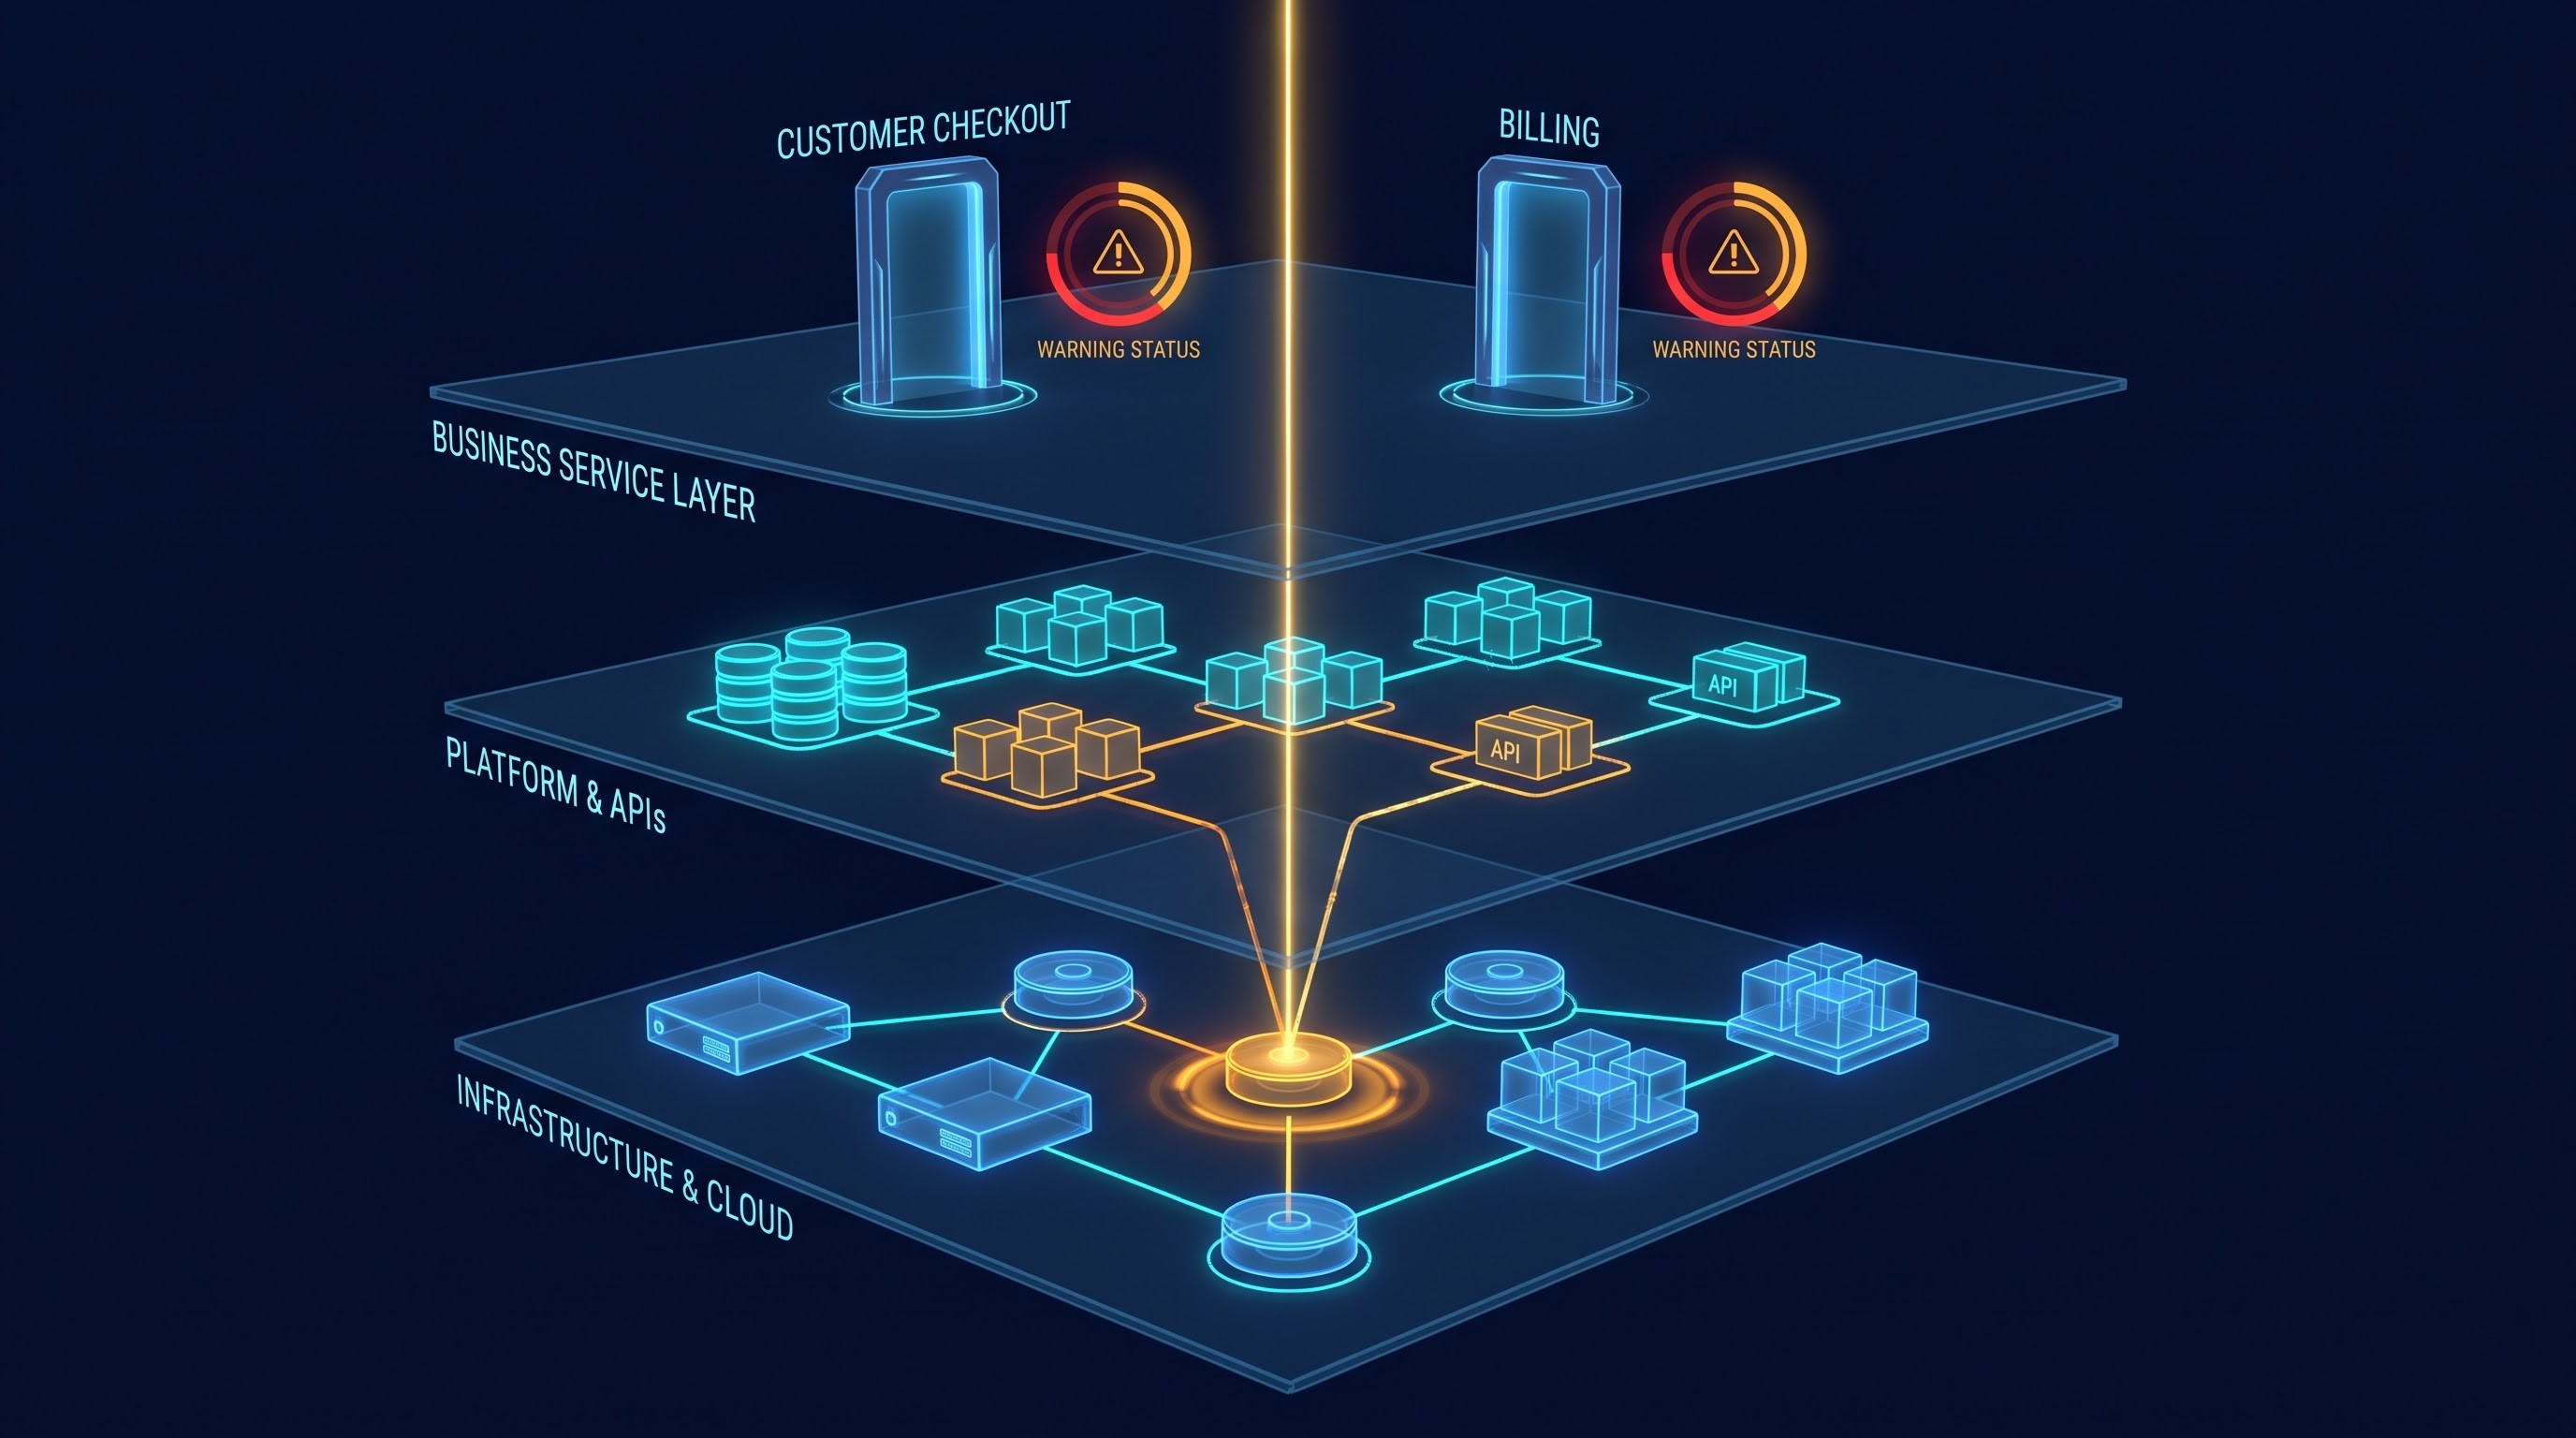
High-level configuration item operational signals that flow thrLcnknown in CMDB are among the big functional strengths of ServiceNow. Through CSDM, ServiceNow obtains the appropriate configuration and business structure of the system in question. So, if for a virtual machine an incident happens, the CGI knows immediately which database is being used, the APIs enjoined to the database, the business service that uses those APIs and the supporting team responsible for delivering that service.
Predictive Intelligence and Machine Learning
After contextualization, sophisticated statistical algorithms and unsupervised machine learning and time series scenarios are employed for data analysis. Such process is capable of creating operational baselines that flag any detected multidimensional anomalies, group events based on topology and timing, and identify the root cause for those events.
Managed Orchestration and Automated Actions Layer
When it comes to getting advantage from insights, context is the key. Thanks to the built-in AIOps technology, It is possible to start handling IT Service Management processes, problem solving, notifications management and Integrations Hub operations. The operations teams have the ability to work with the pre-written runbooks, gain access to the temporary cloud resources, restart services, revert the failed changes and finish the process of error discovery.
Main Features of ServiceNow AIOps
ServiceNow offers a wide range of developed features to enhance operational life cycle.
Smart Event Management and Noise Management
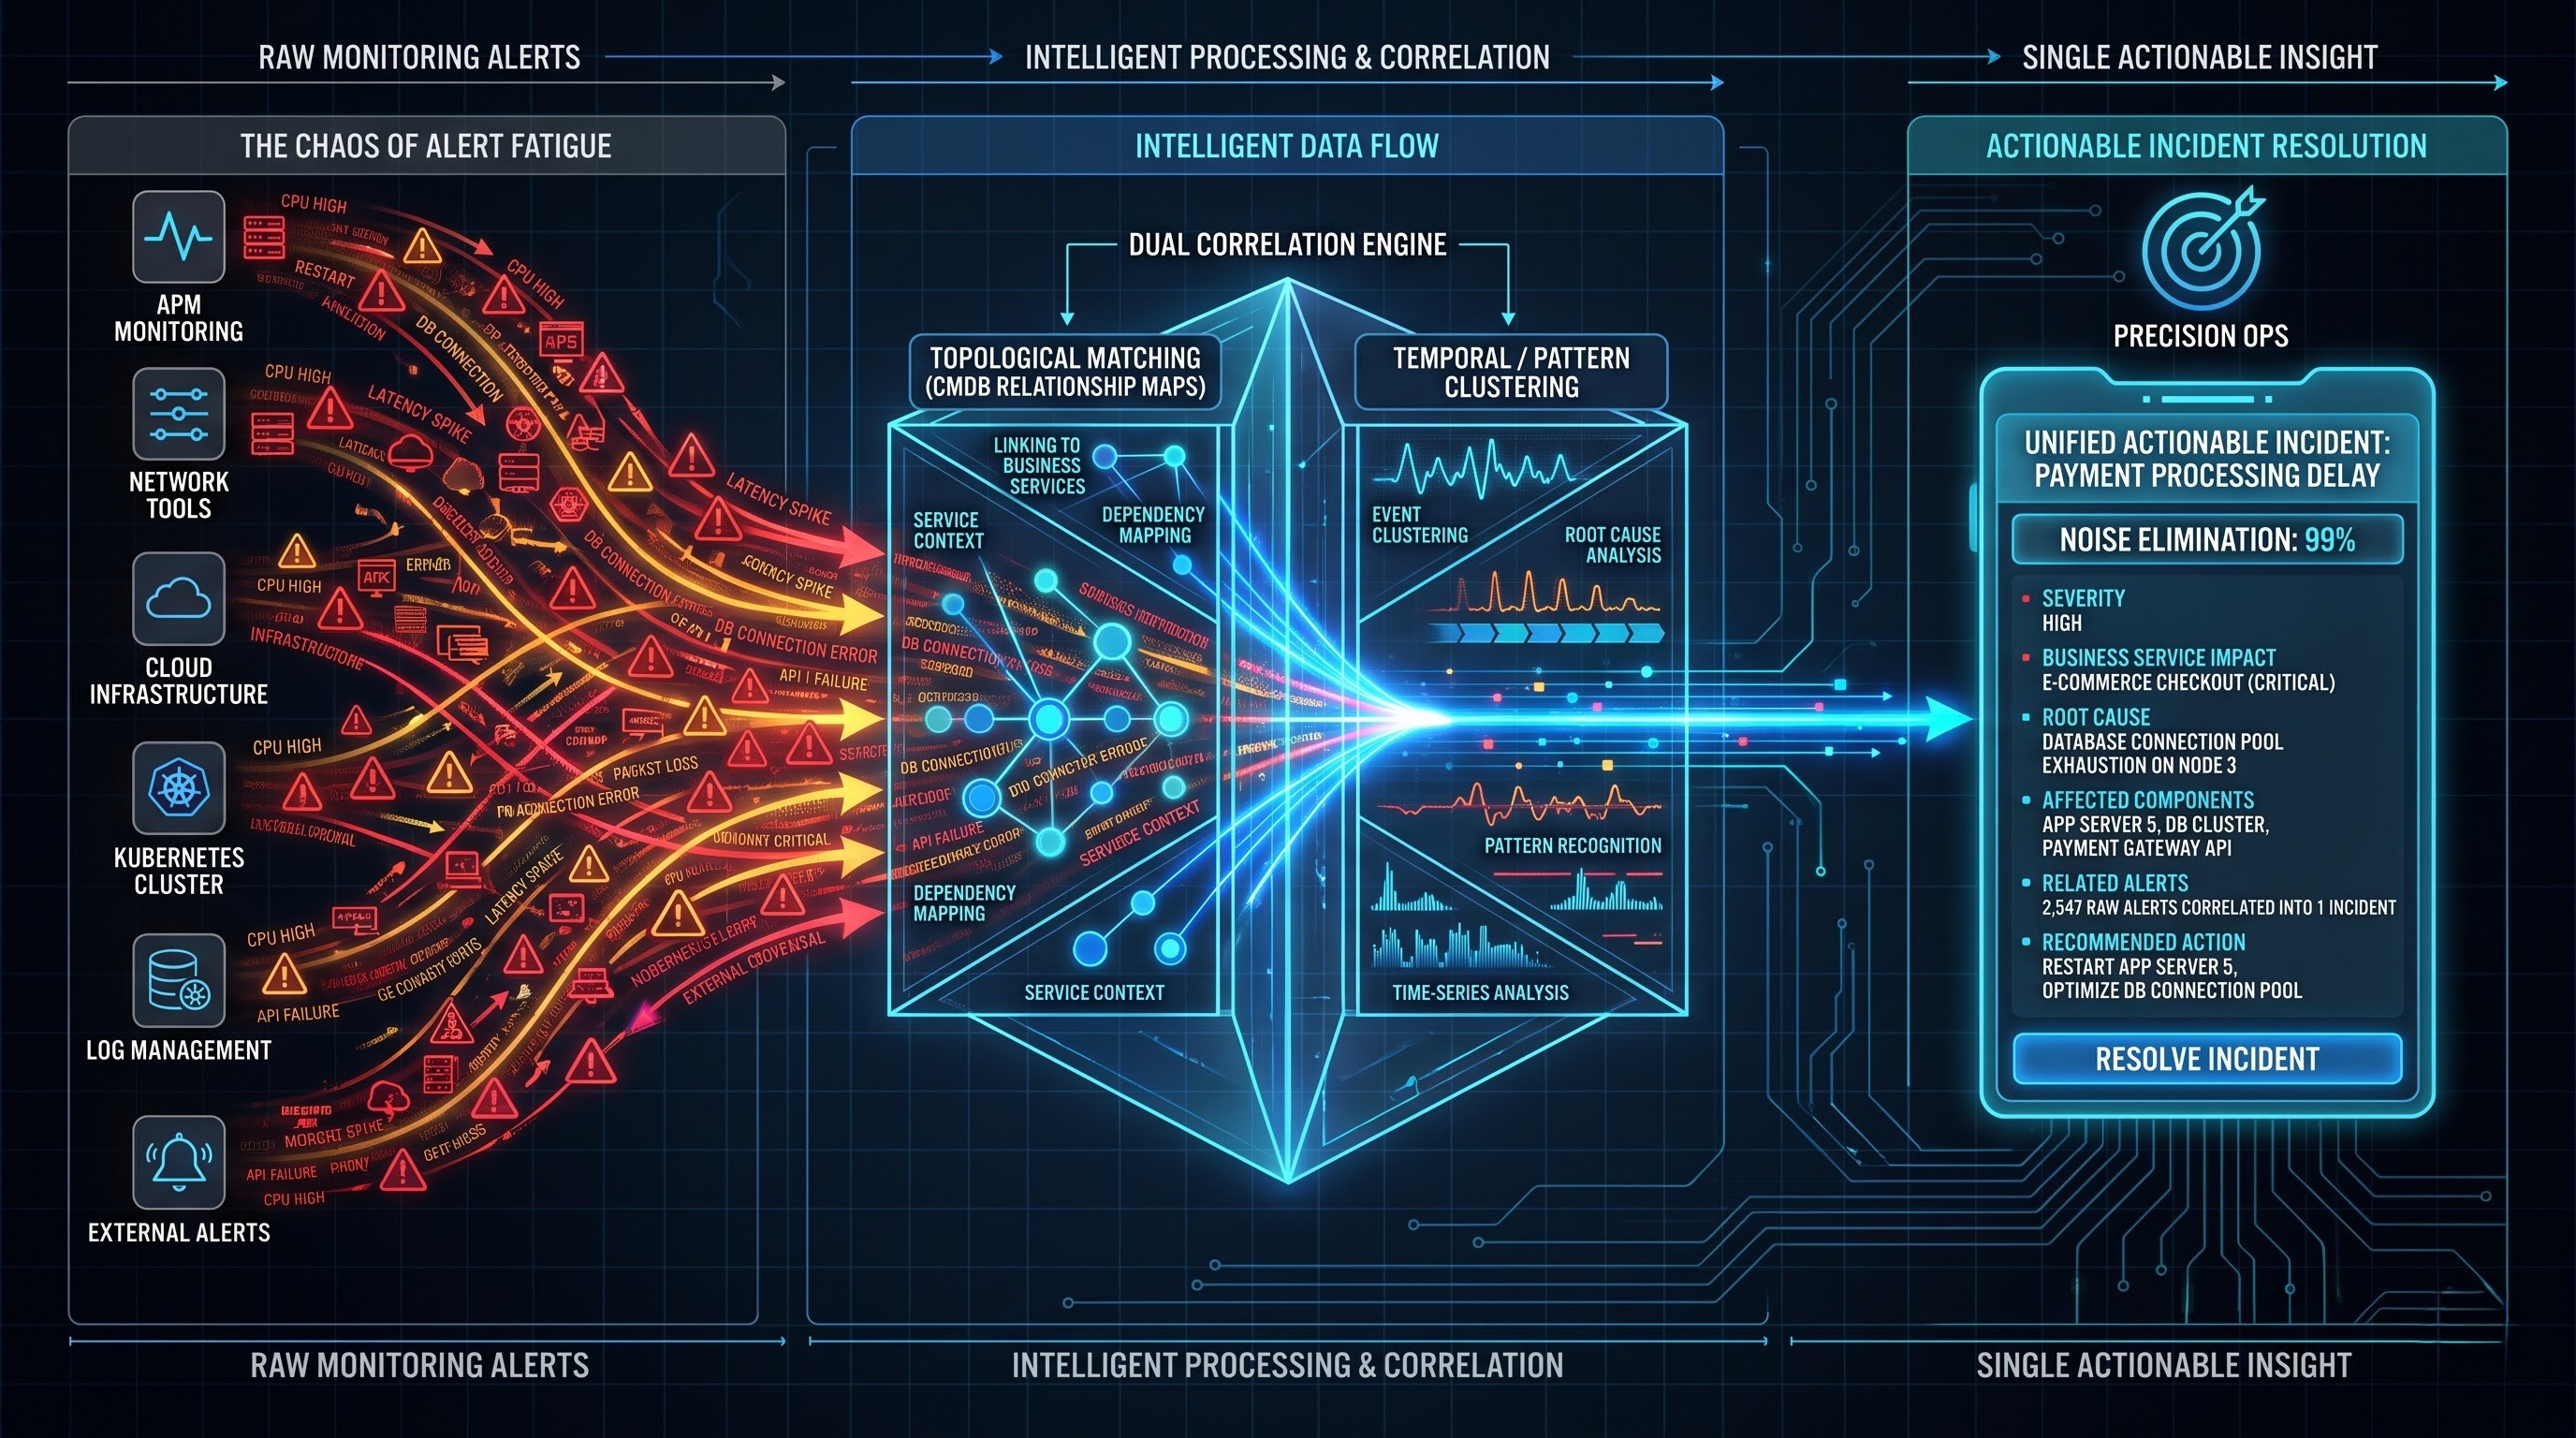
The most advanced event management system by ServiceNow is able to gather the raw operational data from the hybrid organization and educate it with the use of automation filtering, deduplication and alerting.
Topological Relationship: Grouping notifications produced by elements that are either physically, logically or graphically interconnected in the configuration graph.
Temporal and pattern correlation: Notifications that happen simultaneously not taking into consideration the fact the structural relationship type wasn’t recognized before.
This dual-engine system provides exposure reduction rates of 90-99% consistently allowing to reduce alert fatigue significantly.
Dynamic anomaly detection and metric insights
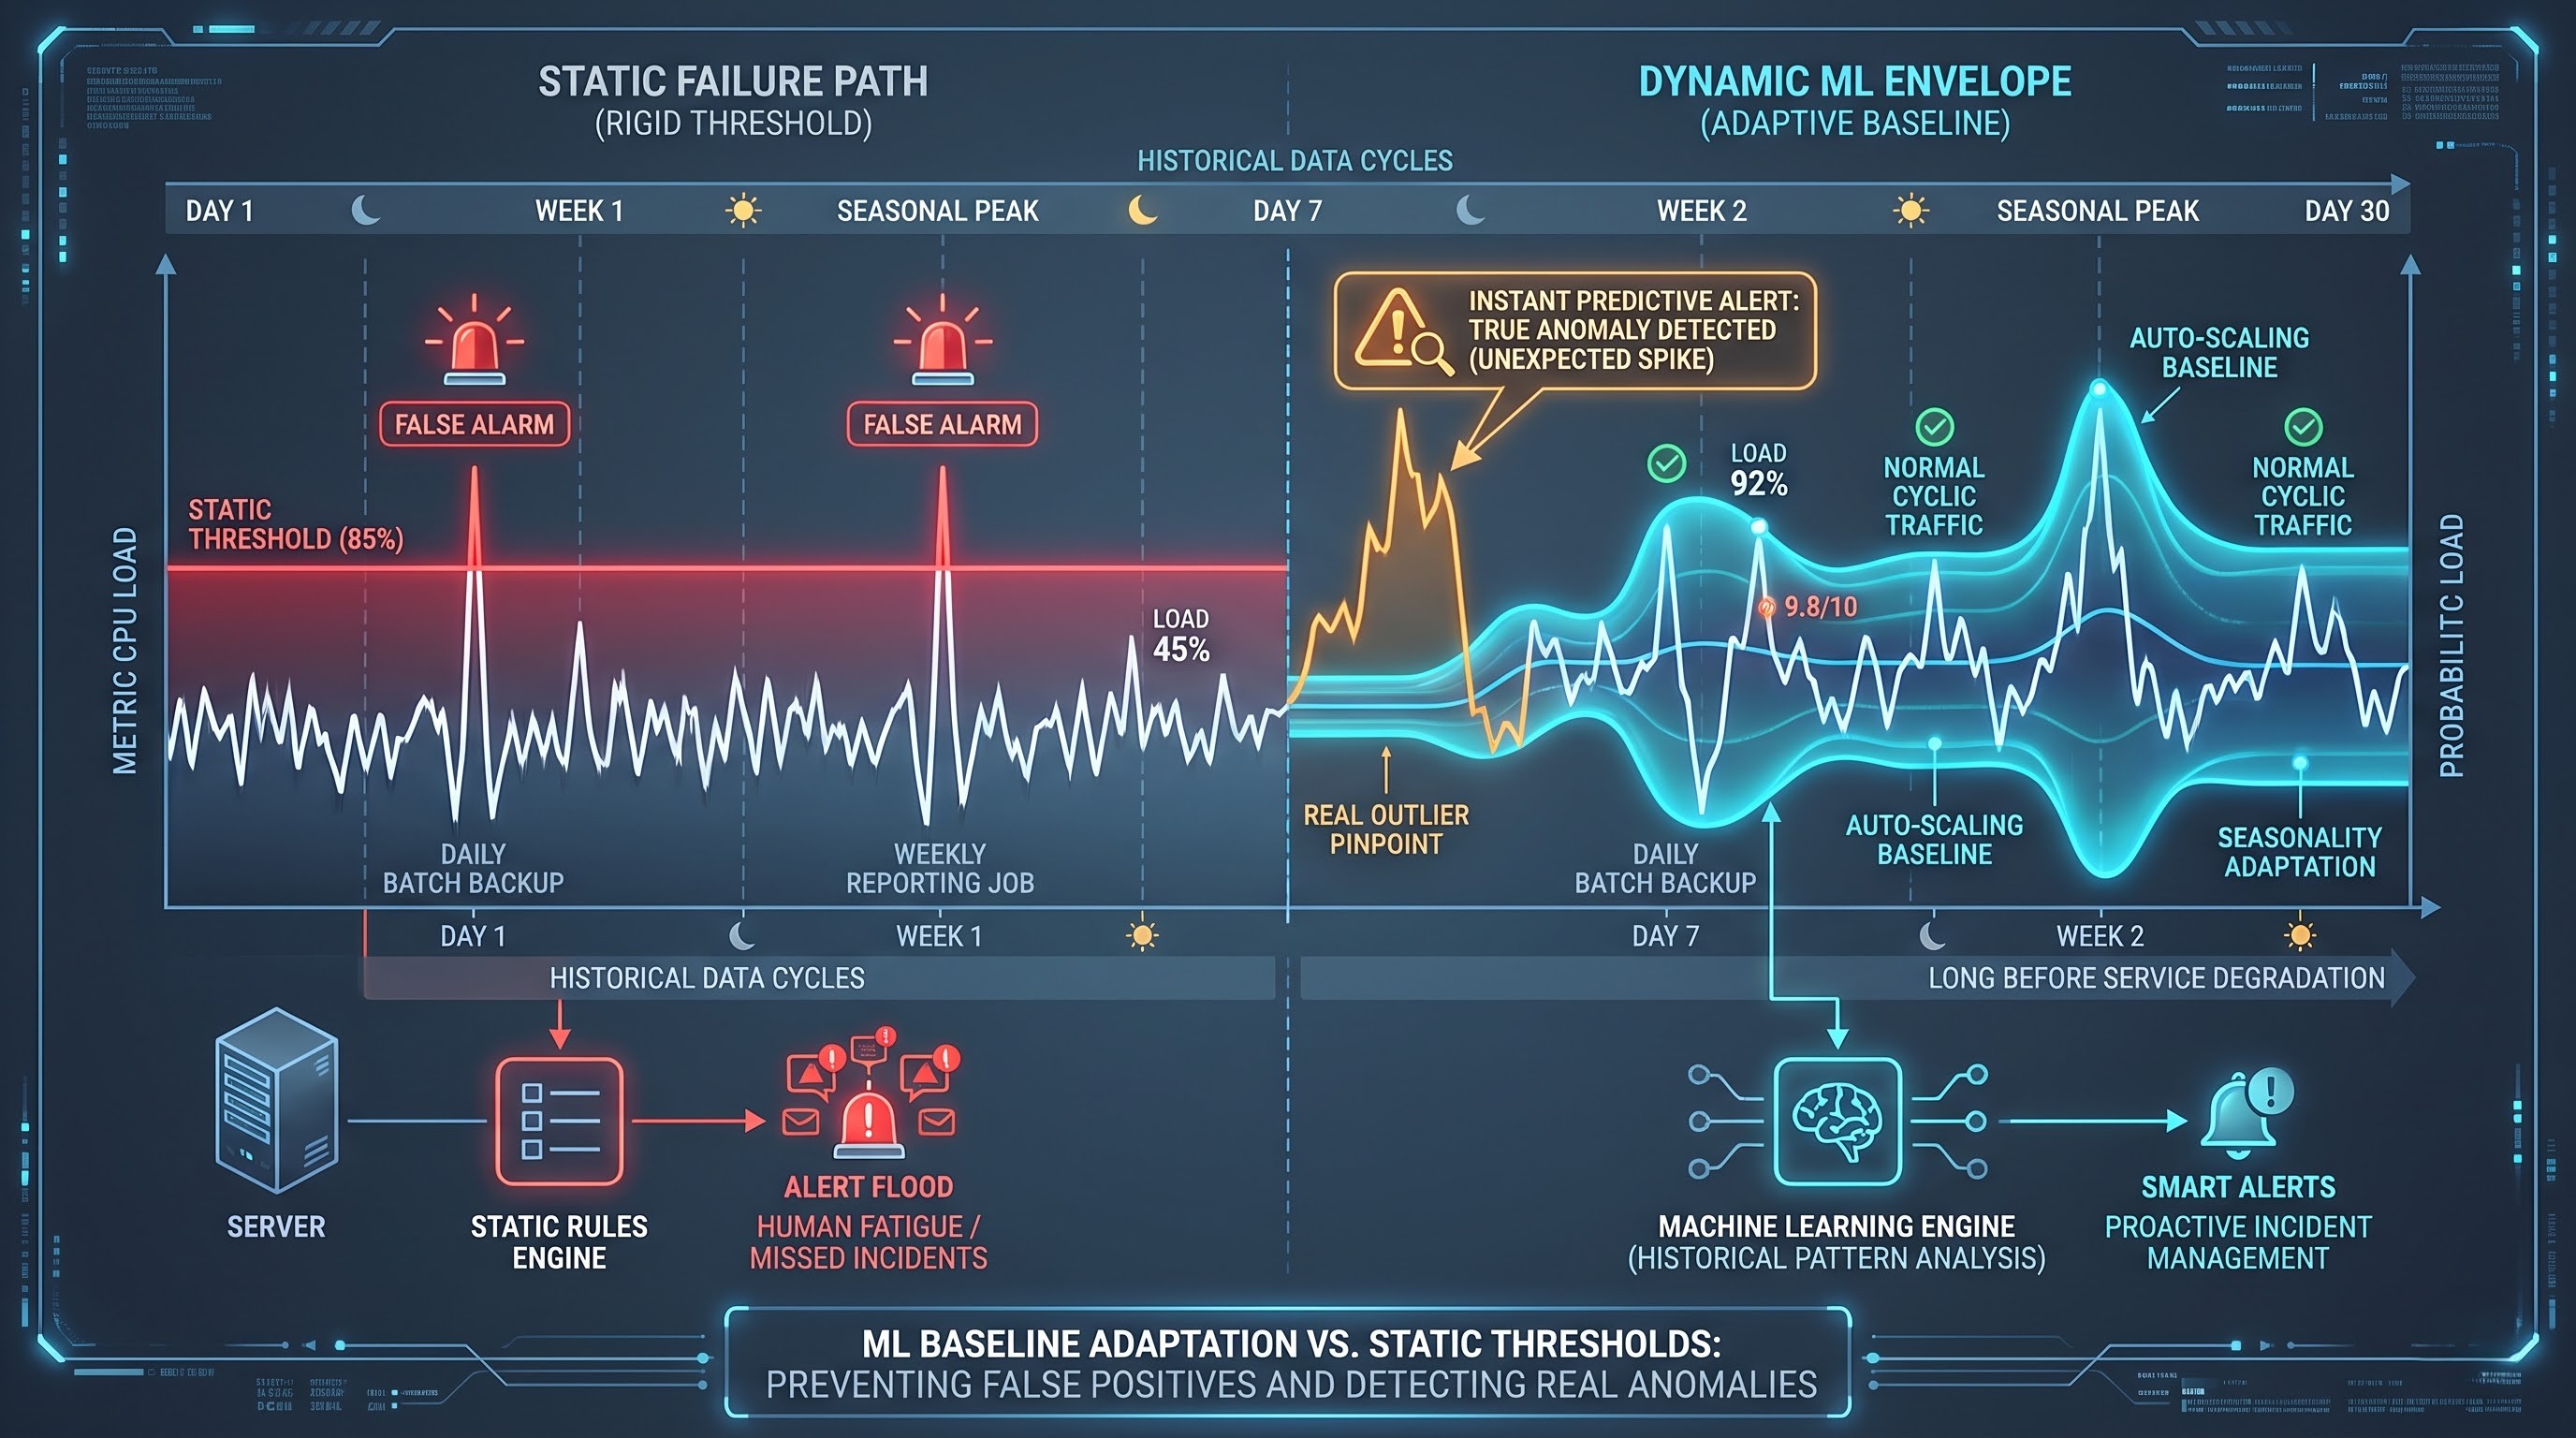
ServiceNow Metric Intelligence employs machine-learning methods for the analysis of continuous time series data instead of using people for configuring static alert thresholds.
The platform identifies trends in seasonal, time-of-day, and time-of-week traffic patterns, as well as historical fluctuations in load in order to establish dynamic threshold values. In case latency, memory usage, length of the queue, or number of operations performed by the disc go out of their normal probabilistic ranges ServiceNow will detect the anomaly long before the users will feel anything.
Automating the process of root cause analysis
In complicated cases of outage of distributed multi-tier systems, many configuration items are reported to be malfunctioning simultaneously. ServiceNow AIOps is responsible for identifying the problem based on analysis of all incoming alerts, incident histories, topological dependencies, and configuration changes.
It allows the system to determine the malfunctioning item, its significance, and make the operator aware of the connections that make it possible to find out why a particular failure occurred. The understanding is provided through the interface of the system used by operators, without wasting any time on finding out what actually happened.
Profound knowledge of behavior & logs analytics
Operational logs can help in diagnosis but they consist of too much data to be reviewed manually. ServiceNow Log Analytics is able to do processing of the logs produced by the user in real time and to convert them to structured analytical indices.
The system is capable of processing billions of records of unstructured information through technology of natural language processing and text clustering. The actions of the operators during the emergencies should be limited to the review of the corresponding logs.
Generative AI and Platform Intelligence
By utilizing advanced generative AI technology, IT Operations Management has sped up its resolution processes. Specifically, the platform utilizes large language models tailored for the specific industry in order to translate complicated technical alerts and complex trace logs into simple ideas.
With the help of ServiceNow, customers get immediate summaries of the incident and the actions taken to correct the same. With structured servicenow training online from OnlineITGuru, juniors and first-level technicians can learn these advanced AI technologies fast enough so that they can troubleshoot issues that were once the prerogative of senior architects only.
Automated Remediation and Self-Healing Procedures
"As digital resilience is an important requirement for business, the automation of workflows is required.” AIOps built by ServiceNow are fully integrated with Flow Designer as well as Integration Hub, enabling it to make use of automated remediation options.
Level One: Contextual Suggestions to the engineer that guide them toward useful articles or runbooks.
Level Two: Providing a single-click button for manual approval to the engineer from the alert console to run a remediation script (such as restarting a web service or clearing log caches) upon verifying the diagnosis.
Level Three: Complete autonomic remediation process- After the anomaly has been confirmed, automated self-healing processes are put in place without human involvement, as long as they are low-risk, not very complicated, and well-tested.
Everything that happened is logged.
AIOps as a part of Change, Incident, and DevOps Lifecycle
A flaw of the traditional way of doing operations is that there is a big gap between the continuous development process and monitoring the systems that are already working. As a consequence, a number of production problems arise due to unauthorized, misconfigured or poorly tested changes made in the respective systems. ServiceNow is a company that practices AIOps along with IT Service Management and DevOps monitoring system, providing a significant bridge that minimizes this gap.
Once an anomaly is identified by the platform, it automatically matches the changed item with recent change requests and ongoing delivery processes. For instance, if you deploy the microservice or install an infrastructure patch, then if you get an alert 30 seconds later, the ServiceNow app will consider this change to be the most likely cause of the problem. Therefore, the engineers do not need to guess whether the software was changed and caused the memory leak; the system is linking the performance issue and the deployment process.
Furthermore, the two-way link is valid for the early change risk assessment as well. In fact, even before the change has been applied in production, standard machine learning algorithms are calculating the risk score based on the historical change data, team metrics, the affected elements, and the timing. If the new change is the same as previous changes that have caused outages, the system will send an alert to the Change Advisory Board to test the change further or shift the time of the deployment.
Advancing Site Reliability Engineering and Enterprise Resilience
Apart from handling tactical incidents, ServiceNow AIOps makes it possible for Site Reliability Engineering to evolve in the enterprise sector. While Site Reliability Engineering is focused on more than simply measuring the number of tickets, an important aspect of it is to achieve balanced operations while ensuring successful achievement of Service Level Objectives.
ServiceNow AIOps provides valuable data for reliability experts so that they understand how the service is performing and the usage of error budgets. Service reliability engineers get insight into the service metrics without the need to wait for incidents to happen. ServiceNow AIOps provides details of error budget usage in real time, as well as enables users to identify patterns, e.g., the latency between clusters that may cause SLA violations.
ServiceNow software product AIOps provides valuable information to incident responders about the events leading to an incident. However, a sequence of events is created that leads to solving the incident, and its team is able to understand when the issue began, what sparked the alerts, and how the issue was ultimately resolved. Information can be applied for code updates, infrastructure upgrade, and creation of new scenarios for test case automation.
Benefits for Business Operations
In terms of the importance of AIOps for a particular company, it can be understood from the technical, financial, and tactical aspects.
An increase in the speed of identification of a type of a problem and its solution.
With the help of ServiceNow the duration of the process of detection and diagnosis in incident management is reduced from a few hours to seconds, as ServiceNow sorts out its active ones into operational duplicates and connects reactive alerts and determines its root cause without considerable effect on the MTTR.
Guarding Your Name and Revenue
In the case of providing online services to clients and businesses, any downtime may be harmful. In addition, when high availability is paramount because of the need to carry out financial transactions, provide medical services, or control the supply chains of transnational corporations, ServiceNow AIOps limits possible losses by detecting anomalies promptly and stabilizing outages.
Minimizing Employee Turnover and Burnout in IT
For operational engineers of conventional network operation centers, their job is quite often stressful and irregular. Noisy network alerts, troubles that arise at night, and repetitive troubleshooting can create significant problems in terms of high turnover. ServiceNow AIOps aids operations groups in improving productivity by performing regular tasks, eliminating false alarms and making plans of action.
Working Together with Different Engineers
In most triage cases, everyone gets defensive during the discussion, including the network engineers as well as the database engineers, application engineers, and infrastructure engineers. ServiceNow AIOps offers a single point of truth concerning CMDB content, which is approximately equivalent to reality and the understanding of incident management. Everyone present has the same service maps and the same timeline of alerts, and they rely on the same reasons.
Principles for success
In order to benefit from ServiceNow AIOps technology, the necessary implementation method should be applied. Companies that treat AIOps as just another software installation will get into trouble. They understand that it is all about transformation.
Start from CMDB structure and service map
Information about relationships plays a pivotal role in AIOps intelligence. In order to make the service map, you need to discover infrastructure resources and map them onto business services according to the Common Services Data Model. AIOps technology can perform temporal correlation of alerts without the service map. However, only by means of the topological service map it is possible to conduct accurate identification of causes and assess the business impact.
Phase-Wise Rollout for Voicing
If you try to hook all the monitoring tools that are available right from the first day and achieve full automation of the remediation processes, then what you will have is an increase in scope and operational confusion. Ensuring that your implementation team has undergone specialized service now training classes via OnlineITGuru will mean that they know the data ingestation rules. Most successful implementations proceed through stages:
Phase One: Ingest events from the primary monitoring tools. Create normalisation rules, focusing on noise reduction and alert deduplication.
Phase 2: Topological, temporal alert correlation, dynamic metric intelligence integration, and automated incident creation for true anomalies.
Phase Three: Employ generative AI to summarize alerts for triage purposes and improve the already-possible root cause models and introduce assisted one-click remediation.
Phase Four: Actioning self-healing for mature, predictable, and low-risk operational issues while optimizing constantly metrics thresholds and correlation algorithms.
Curate the Ingested Data and Decrease Junk Upstream
The first law of artificial intelligence is the law of data quality. If monitoring tools are sending corrupt, badly formatted, or overly redundant events to the platform, then correlation models will yield skewed reports. IT leadership also should have in place regular checks on monitoring agents, phase out obsolete checks and finally establish well-formed telemetry payload definitions before passing them into the enterprise event pipeline.
Governance and automation for safety
Automated remediation can be a highly beneficial technique, but if it is not used properly, it may lead to substantial risks. Organizations should have an effective framework of guidelines within risks management, change control, and rollback tools for any automated action. To gain trust from compliance officers, system engineers, and business managers, IT leaders should implement semi-autonomous actions first and validate their efficacy on multiple cases before starting to conduct fully autonomous process.
Promote the development of the people, processes, and culture
A great cultural shift is needed in transitioning from manually done operations to AI-assisted operations. To address this skills deficit efficiently, IT professionals usually opt to attend hands-on servicenow training classes offered by OnlineITGuru where they will learn how to create CMDB models and understand dynamic anomaly charts. Executives working in IT departments should support this transition as AIOps should be viewed as an extra help in cognitive work rather than an alternative to jobs and workers.
The Future of IT Operations in an Autonomous Workflow
The speed and quantity of operational telemetries will only increase in the future due to moving to distributed enterprise architecture, cloud computing, edge and serverless runtimes. Thus, the future of IT operations will be associated with the development of platforms blending intelligence and action.
ServiceNow AIOps is at the core of these changes. It distances telemetry collection from the topology configuration, service governance, change management, and remediation thus creating an end-to-end platform for autonomous operation. It eliminates the confusion caused by multiple monitoring products paving the way for engineering teams to gain predictive visibility and ensuring that digital technologies of the enterprise are up-to-date, effective, and compliant with business goals. Companies switching to this innovative intelligence-driven approach turn their IT operations from a reactive cost center into an effective tool of digital innovation.